First objective of the JISC-supported Sonex initiative was to identify and analyse deposit opportunities (use cases) for ingest of research papers (and potentially other scholarly work) into repositories. Later on, the project scope widened to include identification and dissemination of various projects being developed at institutions in relation to the deposit usecases previously analyzed. Finally, Sonex was recently asked to extend its analysis of deposit opportunities to research data.


Sunday, 6 November 2011

euroCRIS Membership Meeting – Autumn 2011, Lille, France


  On Nov 2-3 the autumn 2011 euroCRIS membership meeting was held at the University of Lille 3 in Lille, France. Attendees from 14 countries (13 European nations plus Canada) met for two days at the Univ-Lille3 Maison de Recherche for learning about the new CERIF 1.3 version (to be released Dec 2011) and the growing number of CERIF-based CRIS implementations in Europe, with a special focus on French ones (see event programme).

Brigitte Joerg, euroCRIS CERIF Task Group Leader and German Research Center for Artificial Intelligence (DFKI), delivered a CERIF v1.3 tutorial at the beginning of the membership meeting. After a general-purpose introduction to CERIF, CRIS Systems and the euroCRIS Group for first-time meeting attendees, the tutorial went into describing new features in the new CERIF 1.3 release (CERIF versions will no longer be named by their year of release as they were so far). Such features include the so-called Infrastructure entities (Facility, Equipment, Service) that have been added to the already existing CERIF Entity Types, namely Base entities (Project, Person, Organisational Unit), Result entities (ResultPublication, ResultPatent, ResultProduct), Second Level entities and Link entities.


Furthermore, the JISC RIM2 MICE Project outcomes (Measuring Impact Under CERIF) have also been brought into the CECRIF 1.3 release under the Measurement & Indicator section. MICE was one of the RIM2 projects –together with CERIFy, BRUCE and IRIOS- presented last September at the JISC programme workshop in Manchester. MICE finished on July 2011 and aimed to “examine the potential for encoding systematic and structured information on research impact in the context of the CERIF schema. MICE aims to build on previous work on impact by producing a comprehensive set of indicators which will then be mapped both to the CERIF standard and the CERIF4REF schema created by the previous Readiness for REF (R4R) Project”. MICE-inspired CERIF 1.3 updates include creation of a new CERIF table, namely the impact measure table, as well as a set of impact indicators: categories that include such concepts as improving performance of existing businesses, improved health outcomes and cultural enrichment. euroCRIS was also involved in the RIM2 UKOLN-led CERIFy Project, dealing with measures of esteem, whose results were as well inspiring for CERIF new Measurement & Indicator definition.

Another new feature for this CERIF release is the Geographic bounding boxes, which will allow displayed information to be restricted to a given geographic area. Geographic bounding boxes are presently defined as squares, thus leaving room for geolocation improvement in future CERIF versions. Finally, a new Linked Open Data (LOD) CERIF Task Group is being planned by euroCRIS.

As a result from this new features, changes in CERIF 1.3 release include a whole set of new entities (such as cfMedium as a new Document Type) and new attributes, as well as removal of some other outdated attributes. The new CERIF version described at the tutorial was a preview, with features such as XML Data Exchange Format Specification and CERIF Formal Semantics still being worked upon until 1.3 version gets finally released next December.

An euroCRIS Overview Session followed the CERIF Tutorial, along which different members of euroCRIS Board reported recent activity. Keith Jeffery highlighted the euroCRIS Rome Declaration on CRIS/IR integration issued earlier this year and mentioned that while CERIF can generate multiple metadata standards such as DC, MODS, etc, OAR usual qDC-based metadata model was insufficiently accurate, so some integration should be seeked along the model CRIS-Publications OAR-Data/Software OAR.
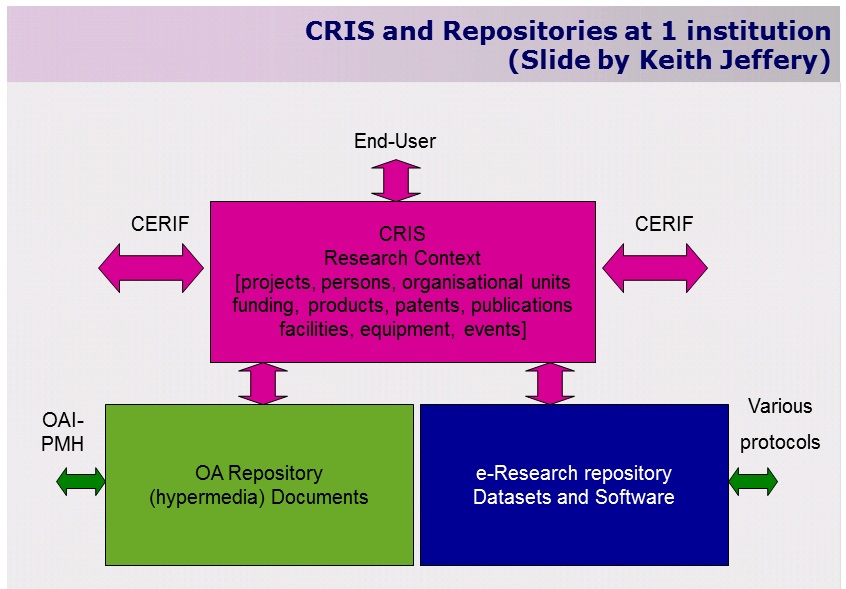

Other euroCRIS-related activity includes EU FP7 OpenAIRE Project moving from qDC to some semi-CERIF standard, as well as the fact that OpenAIRE+ Project will use CERIF. By definition, CERIF serves a multiple-institution scheme (thus allowing for wider context-related information sharing for purposes such as the Research Excellence Framework assessment in the UK), so there’s also a clear need to operate internationally as to demonstrate CERIF interoperability capabilities.

Harry Lalieu, euroCRIS Secretary, announced CRIS2012 Conference to be held in Prague next June, and 2012 euroCRIS membership meetings, which will tale place in Prague just before the CRIS2012 event and possibly in Spain later next year.

Anne Asserson, Universitetet i Bergen and responsable for euroCRIS strategy, announced dataset management as the next environment CERIF will be next moving into (with projects such as University of Sunderland-led CERIF for Datasets paving the way for such move).

Speaking on behalf of Ed Simons, Universiteit Nijmegen and euroCRIS website manager, Keith Jeffery informed the audience a test CRIS is being planned for inclusion at the euroCRIS site, thus allowing for future live-demoing and functionality analysis.

Within the euroCRIS Task Group reports, Brigitte Joerg mentioned the euroCRIS Board-authored paper “Towards a Sharable Research Vocabulary (SRV) - A Model-driven Approach” having been presented at the Metadata and Semantics Research Conference (MTSR 2011) held last October in Izmir, Turkey. A preliminary meeting with Virtual Open Access Agriculture & Aquaculture Repository (VOA3R) Project was also recently held in Madrid in order to plan the future euroCRIS Linked Open Data (LOD) Task Group.

Nikos Houssos, NDC Athens and Task Group Projects leader mentioned running EC FP7 Projects euroCRIS is involved into, such as ENGAGE, dealing with Open Access to Public Sector Information, EuroRIs-Net, one of whose outputs is providing an online CERIF database of RI stakeholders, and OpenAIRE+. UK/JISC Projects such as CERIFy, CRISPool, BRUCE, IRIOS, MICE or RMAS were also cited as a proof of CERIF gradually becoming a common standard for RIM Programme Projects. Many of those projects are having an active euroCRIS involvement.

Danica Zendulková, CVTISR and CRIS-IR Interoperability Task Group leader, announced upcoming TG work along lines such as defining usecases for CRIS/IR interoperability, defining a model of integration interface (including XML data exchanges and web services), implementng an authority file model with attached persistent ID and promoting cooperation between CRIS/OAR communities.

Finally, David Baker, CASRAI and euroCRIS Architecture Task Group manager explained the way towards the Reference CRIS implementation. According to implementation plans, a test CRIS should be available at the euroCRIS site on June 2012.

Several sessions –see euroCRIS meeting presentations- followed the euroCRIS Overview, summarizing recent and forthcoming developments in CRIS and CERIF implementation. An interesting discussion was also held, led by Joachim Schöpfel, on teaching CRIS Systems to his Information Science students at Université de Lille and on potential CERIF application to the teaching environment and scholarly activities beyond research.

A particularly relevant presentation –as it described CERIF-based CRIS implementation in the UK, where CERIF standard adoption has been most successful so far– was UKOLN Rosemary Russell’s “CERIF UK landscape” (final report to be formally published later this year by UKOLN-University of Bath). Some figures were mentioned at the presentation: 17 PURE/Atira CERIF-based CRIS were implemented in the UK along last year, plus 5 Converis/Avedas CRISes and a large number of Symplectic Elements.


The CERIF UK Landscape Project carried out a set of seven interviews among ‘CRIS Project managers’ from different institutions - based at the institutional Research Office (2), Library/Info Services (4) or IT Department (1)- in order to gather their views on the implementation process, CRIS reception by end-users (researchers) and staff, plus experience on CERIF and integration with Institutional Repositories. A summary of the –often not so encouraging– answers is available at the presentation, CERIF being perceived by many as a far too complicated standard whose management would rather be handed over to the CRIS commercial provider. It is a fact however that institutions running a CERIF-based CRIS are in a much better position to deal with the REF requirements.

Wednesday, 19 October 2011

MaDAM: A JISC MRD Project for Research Data Management in the Biosciences... on the move


  Being in Manchester for the JISC Research Information management (RIM2) event, Sonex didn’t miss the opportunity it provided for paying a visit to the University of Manchester John Rylands University Library and meeting the JISC MRD MaDAM Project team. The 'MaDAM Pilot data management infrastructure for biomedical researchers at University of Manchester' has been funded by the JISC Managing Research Data Programme from Oct 2009 to Jun 2011 and has provided an inspiring example on how to start building an institutional research data management infrastructure almost from scratch.

In order to start developing this RDM infrastructure (see the Project Final Report for details), MaDAM focused on a set of research groups from the biomedical sciences strand aiming to learn about the ways they dealt with data management and to provide them -with their own close involvement- with tools to improve and standardise such practices. Selected research groups -Electron and Standard Microscopy group and Magnetic Resonance Imaging (MRI) Neuropsychiatry Unit- were chosen due to their common need to deal with large images as their main source of research data.

Project focus on a rather narrow research scope was one of the keys to its success - due to its resulting ability to define common ways for dealing with the information, eg at metadata level. The MaDAM planning included further RDM strategy extension to other research groups within the UoM based on the lessons learnt from its application to the few initially selected groups. The MiSS Project (MaDAM into Sustainable Service), funded by the JISC MRD Programme 2011-2013, will be dealing with the RDM strategy extension and widening into the whole of the UoM research works along next years.


An Oracle APEX-based research data management application was developed by MaDAM for the concerned UoM research groups -later to be revamped in order to adapt it to the regular software standards applied at UoM. Frequent meetings were held with researchers along the aplication development so their feedback could be collected to ensure it would meet their needs. Storage needs per researcher per year were estimated (at around 500 GB), a metadata standard for specific data description was devised and stored in the RDM application, and work was carried out with interoperability isses in mind, both with the University CRIS in order to automatically populate Grant and Project information attached to datasets, and with the UoM Fedora-based eScholar IR, where final-version datasets would be transferred via Sword for dissemination, sharing and re-use.


Along the MaDAM Project several conceptual needs regarding the implementation of a solid RDM infrastructure across the UoM (and beyond) were identified -which were later included in the Project Final Report- the main two of which are the following:

- Some means of academic recognition of data-related work by researchers should be put in place in order to promote their involvement in RDM schemas and the adoption of common practices,

- A research data management policy should be adopted by the University of Manchester similar to the one issued at U Edinburgh so that some guidelines are established for providing support to researcher RDM tasks.

MaDAM gradual roll-out to other UoM research groups will face a set of challenges, research data being so discipline-specific. However, plans for such an extension and for ensuring the required institutional support for such a move were designed along MaDAM development -which saw the interest in taking part in the pilot project by a number of additional UoM research groups- and extension work will start soon.

Friday, 14 October 2011

CERIFying Research Information Systems... and Research Data


  A couple of weeks ago Sonex was attending the JISC Research Information management (RIM2) event at MCC Manchester. It was a very good opportunity to review the four JISC-funded projects (BRUCE at Brunel, IRIOS at Sunderland, CERIFy at UKOLN and MICE at KCL) dealing with CERIF implementation for research information management purposes. A report for the event should be shortly available, along with the slides presented at the event.

Along this one-day meeting the CERIF for Datasets (C4D) Project was mentioned as an IRIOS Project extension to dataset management at the University of Sunderland. As stated in the project presentation, C4D aims to 'CERIFy' existing research dataset metadata conventions, and hence provide access to research data in an environment which also holds information on research projects and research outputs. C4D will also explore the commonality of research dataset metadata, and how much can be represented in CERIF.

Saturday, 17 September 2011

Progress on Researcher ID initiatives: IRISC 2011 Helsinki


The problem with names...

Prof. Carlos Martínez-Alonso is a renowned Spanish senior biochemist. He was actually President of the Spanish National Research Council (CSIC) when the Berlin Declaration was signed by the institution in January 2006. Prof. Martínez-Alonso has published hundreds of papers in high impact factor journals. However, when retrieving a complete list of his publications from PubMed database, you find out it is not possible unless several parallel author queries are carried out: there is a Martinez-A C entry under which most of his publications get listed [222]. But then there's also Martinez-Alonso C [21] and even Alonso CM [1].

It might be argued it's all about funny Spanish names with two surnames in them. That's a problem alright. Not just for Spanish names though: it's quite the same for Portuguese/Brazilian authors as well. Not to mention transliteration of Asian author names (see "Which Wei Wang?" Phys Rev 2007 editorial). PubMed is presently running its Author ID project in order to tackle this problem, which is by no means exclusive of theirs: around 2/3 of the over 6 million authors in MEDLINE share a last name and first initial with at least one other author, and an ambiguous name refers to 8 persons on average (Torvik and Smalheiser, "Author name disambiguation in MEDLINE").

Name disambiguation and proper attribution is a well-known problem in the scholarly publishing ecosystem. There have been and there are lots of initiatives trying to tackle this complex issue at subject, institutional or even national level - with remarkable success in the case of the Dutch Digital Author Identifier (DAI).

However, this is not an issue to be tackled at national nor subject level, but globally. Commercial stakeholders such as ThomsonReuters or Elsevier-Scopus are then in a privileged position to implement some international author unique identification schema. From a knowledge discovery viewpoint there are however some problems in this commercial-stakeholder approach: the ResearcherID, ThomsonReuter's author identifier, will provide seamless integration with ISI Web of Knowledge and show all author publications registered in that database, but will otherwise leave out most of the research output.

Some joint effort between public institutions and private stakeholders (remarkably publishers) must therefore be attempted to unify the multiple author identification standards and devise a single, comprehensive one at a global level. And that's where ORCID comes in.

  
... and strategies to tackle it: IRISC 2011 workshop

The Open Researcher & Contributor ID (ORCID) initiative started in Dec 2009 as a non-profit organisation. Currently over 240 participants have joined the project for developing the one research identifier which is not limited to discipline, institution or geographical area. Many other projects are working in this issue at the same time (such as abovementioned discipline-based PubMed Author ID and Cornell University initially institutional then grown to national VIVO initiative).

ORCID and VIVO were two of the main topics of the IRISC 2011 Workshop on Identity in Research Infrastructure and Scientific Communication held this week (Sep 12-13) in Helsinki - see the event programme with attached presentations. Gudmundur "Mummi" Thorisson, Research Associate at University of Leicester and member of ORCID Technical Working Group, was IRISC 2011 main organizer.

There were two major IRISC 2011 strands: identity regarding knowledge discovery and identity for security & access control (focusing mainly on identity federation). A third big cross-issue along the Helsinki event was research data management, from three different perspectives:

i) dealing with a rapidly increasing amount of biomedical research data (Andrew Lyall, EMBL, ELIXIR Project)

ii) dealing with clinical research sensitive data (see Tony Brookes GEN2PHEN Project presentation)

iii) benefits the ORCID implementation might bring to research data attribution and management (mentioned in most ORCID-related presentations and discussions along the workshop)


There were several presentations dealing both with ORCID and closely resembling VIVO initiatives. Martin Fenner, Hannover Medical School and member of ORCID Board of Directors announced the ORCID registration service will start operating in spring 2012. ORCID will be open: researchers will be able to manage & maintain their profiles, filed data will be openly available, ORCID-related software will be released as open source, and researchers will control their privacy settings (with a chance too to share with particular members). Finally, for ORCID identity definition purposes, self-claim as well as external claiming sources will be used.

Brian Lowe, University of Cornell, presented the already running NIH-funded, institutionally-managed VIVO initiative. VIVO is aiming for an extensible semantic model-based more comprehensive approach than ORCID. However, links have already been established between both initiatives and ORCID is hoping to build upon VIVO success in the US.


Breakout sessions were held on IRISC Day 2 on the workshop's two main strands: "Unique identifiers and the Digital Scholar" (lead by Cameron Neylon and Jason Priem) and "What do researchers need from the authentication and authorisation infrastructure (AAI)?" (chaired by Michael Linden, CSC). Breakout session #1 was devoted to discussing potential tools and services to researchers ORCID could provide in the short term (6 months from adoption). Several groups were set up for the purpose and proposed ideas were later voted and discussed for selecting three main future worklines for ORCID to deal with. The proposed and selected use cases were the following:

-> data submission to repositories (multiple task attribution)

service to enable attribution or comment

pre-populate ORCID data

-> manuscript/grant tracking system

ORCID app gallery

-> automatic CV maintenance (potentially including data citations in CVs)

connecting different author research & social network profiles

Selected ORCID use cases were later introduced by Cameron Naylon along his talk 'ORCID and researchers' at the second annual ORCID Outreach Meeting held at CERN on Sep 16th, 2011.

Monday, 29 August 2011

Research data management in crystallography at the XXII IUCr Congress


  On Aug 29th a session on research data management will be held at the XXII Congress of the International Union of Crystallography (IUCr2011). The session will feature talks by Brian McMahon (IuCr), Brian Matthews (I2S2 Project), Peter Murray-Rust (CrystalEye), John Westbrook (wwPDB) and Nick Spadaccini (DDLm). Peter Murray-Rust will deliver a talk along the session on Open Crystallography.

Friday, 26 August 2011

STM research data management and the Quixote Project


  A one-day seminar was held yesterday Thu Aug 25th at the Zaragoza Scientific Center for Advanced Modeling (ZCAM) on research data management and the Quixote Project for data management in Computational Chemistry. The session, entitled “Research data management: The experience of the Quixote project for Quantum Chemistry data. Can it be extended into a collection of research data management repositories?”, was attended by a rather diverse group of researchers (both computational chemists and from other disciplines) and repository managers, aiming to learn about research data management initiatives and specifically about the progress of the Quixote Project, in which two researchers from the University of Zaragoza and the CSIC Institute of Physical Chemistry "Rocasolano" are involved.

The Quixote Project (see paper "The Quixote project: Collaborative and Open Quantum Chemistry data management in the Internet age", in press with the J Chem Inf) is developing the infrastructure required to convert output from a number of different molecular quantum chemistry (QC) packages -such as NWChem or Gaussian- to a common semantically rich, machine-readable format and to build repositories of QC data results.

The session started with an introduction to "STM Research data management initiatives in Spain and abroad" delivered by SONEX member Pablo de Castro, in which different national approaches to RDM were presented based mainly on the information collected at the JISC MRD Programme International Workshop held last March in Birmingham.

Different approaches to data management taken from the JISC and SURF Foundation were discussed at Q&A time: for the JISC, datasets are assets per se, regardless of where they are attached to a research paper as supplementary material, whereas the 'Enhanced publication' approach from the SURF Foundation in the Netherlands, regards datasets mainly as digital objects connected to research publications. Some emphasis was made on the fact that the upcoming OpenAIREPlus European project shares the SURF approach.

Two presentations on the Quixote Project followed, "From Databases in QC 2010, ZCAM, Sep 2010 onwards: a brief history of Quixote" by Jorge Estrada and "The Quixote Project: a pioneering work in managing Computational Chemistry research data" by Pablo Echenique. Both Quixote project members explained the results, the challenges and the cooperation opportunities of this non-specifically-funded RDM project, engaging in a fruitful dialogue with the attending researchers and repository managers on how the QC data assets could be best managed.

Finally Peter Murray-Rust closed the morning interventions with some reflections on the subject "Entering a new era in data management" - see his blogpost for a summary of his ideas.


In the afternoon there were joint debates on how to improve implementation of research data management initiatives. Researcher motivation for dataset sharing was extensively debated: this motivation should ideally not just arise from a given funding agency actually requiring those data to be made available, but from the sheer advantages (as summarized by Peter Murray-Rust) that doing so would bring to the research practice and communication ("improving methodology").

An independent debate session was held for discussing how to start developing some kind of research data management infrastructure in those countries where work in this area is presently beginning. These are some recommendations that were put together by the participants in the debate:

- Some workgroup of (not just library-based) IT professionals should be put together for analysing the current infrastructure and the opportunities for launching new initiatives upon potentially reusable pre-existing ones,

- It would be advisable to analyze the researcher behaviour and needs in terms of storing their datasets into international platforms for data sharing (in case they are available for their specific discipline),

- It would be interesting to examine the motivation for data sharing from research groups in different research areas, so that initial efforts to develop data management infrastructures can start working with those areas more willing to share their data (Earth Sciences recurrently showing up when analysing the international perspective),

- Pioneering initiatives for providing services to STM researchers regarding data handling and storing from given Institutional Repositories (such as eSpacio UNED and Digital.CSIC) should be highlighted as a role model to be spread,

- The OpenAIREPlus/SURF Enhanced papers approach could be a good starting point for Institutional Repositories to work at, by finding out which of their presently filed papers have supplementary data attached at the journal site and trying to independently manage those ones,

- A need was detected along the session talks with researchers for a dataset management system at research centres for basic internal organisation purposes. Datasets filed in this internal storage system may or may not be aimed for publication,

- Production and publication of potentially citable datasets should be acknowledged as a relevant scientific contribution for research assessment purposes,

- There are big differences in needs, procedures and required infrastructure regarding data management between Big Science and long-tail science (the greater part actually being groups of three researchers in a lab with specific needs of their own),

- The Library is a potential supplier of know-how on data processing and storing for researchers, and that role should be promoted within the institutions,

- The Spanish e-Research National Network, mostly dealing with Grid and supercomputing initiatives, might be a good workgroup infrastructure for pioneering data management initiatives in Spain,

- There are real collaboration opportunities between the Quixote Project and the research information management infrastruture at the University of Zaragoza (two IRs being currently available, Zaguan at the University and Digital.CSIC at the Spanish Nacional Research Council, CSIC),

- Research staff (mainly PhD students) getting involved in the management and operation of the dataset information management systems (such as Chempound data repository at the University of Cambridge) seems a prerequisite for the success of the data management initiatives

- Due to the specific data features for various research areas, the incipient data management infrastructure available is more developed for the Social Sciences and Humanities than for STM research areas.

Saturday, 20 August 2011

Repositories and CRIS: Working Smartly Together


  Due to recent involvement in other OA repository-related activities at the University of Khartoum, reports at this blog on recent events such as the 'Repositories and CRIS: Working Smartly Together' workshop organised by RSP last Jul 19th in Nottingham and the 4th edition of the Repository Fringe in Edinburgh were slightly delayed. Good news about it is that interesting reports on these events have been published in the meantime (see the RSP event review by Gareth J. Johnson at UKCoRR blog). This will allow Sonex to take a different approach to the reporting, making it more of a reflection than of a description, as well as covering the conference followup.

One of the subjects discussed along the Reposit project session within the Conference at EMCC was what mailing list or discussion group should replace the reposit@googlegroups.com forum for discussing IR and CRIS-related issues once the RePosit project comes to an end. Several options were considered, from using already existing lists such as UKCoRR's or ARMA's, to creating a new Super-CRIS list at JISC mail such as cris-super@jiscmail.ac.uk. Steps are being taken after the workshop to make this new list available.

The REF is working as a very strong driver towards CRIS implementation (with CERIF format being extensively considered in order to become a standard, see Marc Cox's presentation). A good number of HEIs do now operate a CRIS as a result (either commercial, in-house built or an extension of their EPrints repository). That is the good news. The not so good ones may be the fact that due to CRIS systems offering an enhanced collection of features, RIM infrastructure managers are starting to wonder whether an Open Access repository (usually managed by the Library) isn't becoming a somehow redundant piece of software, with most of its functionalities being increasingly covered by the CRIS (managed at the Research Offices). Repository phase-out is thus beginning to be discussed at given institutions for integration and optimization purposes. However, as Janet Aucock (University of St. Andrews) writes in the reposit@googlegroups list, even if the degree of overlap between repositories and CRIS systems may be large and growing, there are still features a CRIS will not be able to deliver:

"(...) Another point is to do your homework really well and make absolutely sure that the CRIs can deliver everything that a repository can do. Can it provide established permanent identifiers for items? Can it handle embargoes effectively? What about stats? Does the discovery interface in the portal display all the metadata that you need with regard to open access full text eg rights statements etc. These are small details which we take for granted but are not always embedded into the CRIS. CRIS software is still evolving too, and perhaps not all the functionality necessary is there yet. Another aspect of this is the question of the interfaces for users and discovery. Is the CRIS successfully harvested or crawled by search engines. Is it ranked appropriately. Can it expose metadata appropriately to other services where required? Can it isolate metadata with full text attached/open access full text attached and allow that set to be harvested and reused? We know that our own CRIS supplier is still working on adding all the "repository" functionality that they think is needed for their product. But at the moment I don't know the fine detail of this".

Besides R4R/CERIF4REF Project at KCL mentioned by Marc Cox, other projects also dealing with CERIF implementation regarding CRISes were mentioned such as MICE for Measuring Impact under CERIF, or the BRUCE Project (Brunel Research Under a CERIF Environment) that was presented at the 2011 euroCRIS meeting in Bologna last May (see Sonex post on the two recent euroCRIS meetings in Italy).

Another interesting outcome of this RSP event was the opportunity to learn from local SHERPA RoMEO team about the RoMEO API new v2.8 version and the release of the SHERPA RoMEO Publisher's Policy Tool, that will allow publishers to directly define their RoMEO policies via an embedded portal in SHERPA (actually presented next day, Jul 20th, at the 'RoMEO for Publishers' event in London).

Finally, a poster was featured in the event poster section called “SICA: A CRIS with an embedded Repository working for the innovation in Andalusia Region (Spain)”. With this integrated system for recording scientific production of the researchers belonging to nine universities, research organizations, technology centres and other scientific institutions of the Andalusia region in Spain, the National & Regional CRIS/IR integration initiatives (as recorded by Sonex in its May'2010 post) keep growing. This particular CRIS initiative is being developed within the European SISOB Project on -yet again- how to measure the impact of science in society.

Besides this -not thorough nor systematically updated- Sonex list of National & Regional CRIS/IR integration initiatives, a comprehensive list of 'CRIS + Repositories in the UK' is being put together as a Conference followup. When complete (it's open for any missing one to be filled in) the list will join the RSP Wiki where Institutional Repositories in the UK are already listed as to provide a clear picture of existing infrastructure.